
Incorrect AI responses in the service area jeopardize decisions. When it comes to warranty claims or maintenance requests, generic AI models often provide inaccurate information: nonexistent fault codes, incorrect contract details, or inappropriate maintenance steps. The reason: Such models are based on probabilities, not on reliable facts. A standalone knowledge base like Service Decision Intelligence (SDI) addresses this issue by consolidating data from IoT, ERP, and CRM systems and making AI decisions transparent.
Key points:
- Problem: Generic AI models tend to hallucinate because they lack specific service data.
- Solution: SDI provides a central intelligence layer with source citations and confidence scores.
- Result: Faster, more precise decisions that are auditable and AI Act-compliant.
In practice, it has become clear that SDI not only streamlines day-to-day operations in customer service but also lays the groundwork for automation.
A typical scenario: Claims triage with and without SDI
Here’s How Claims Triage Works Today
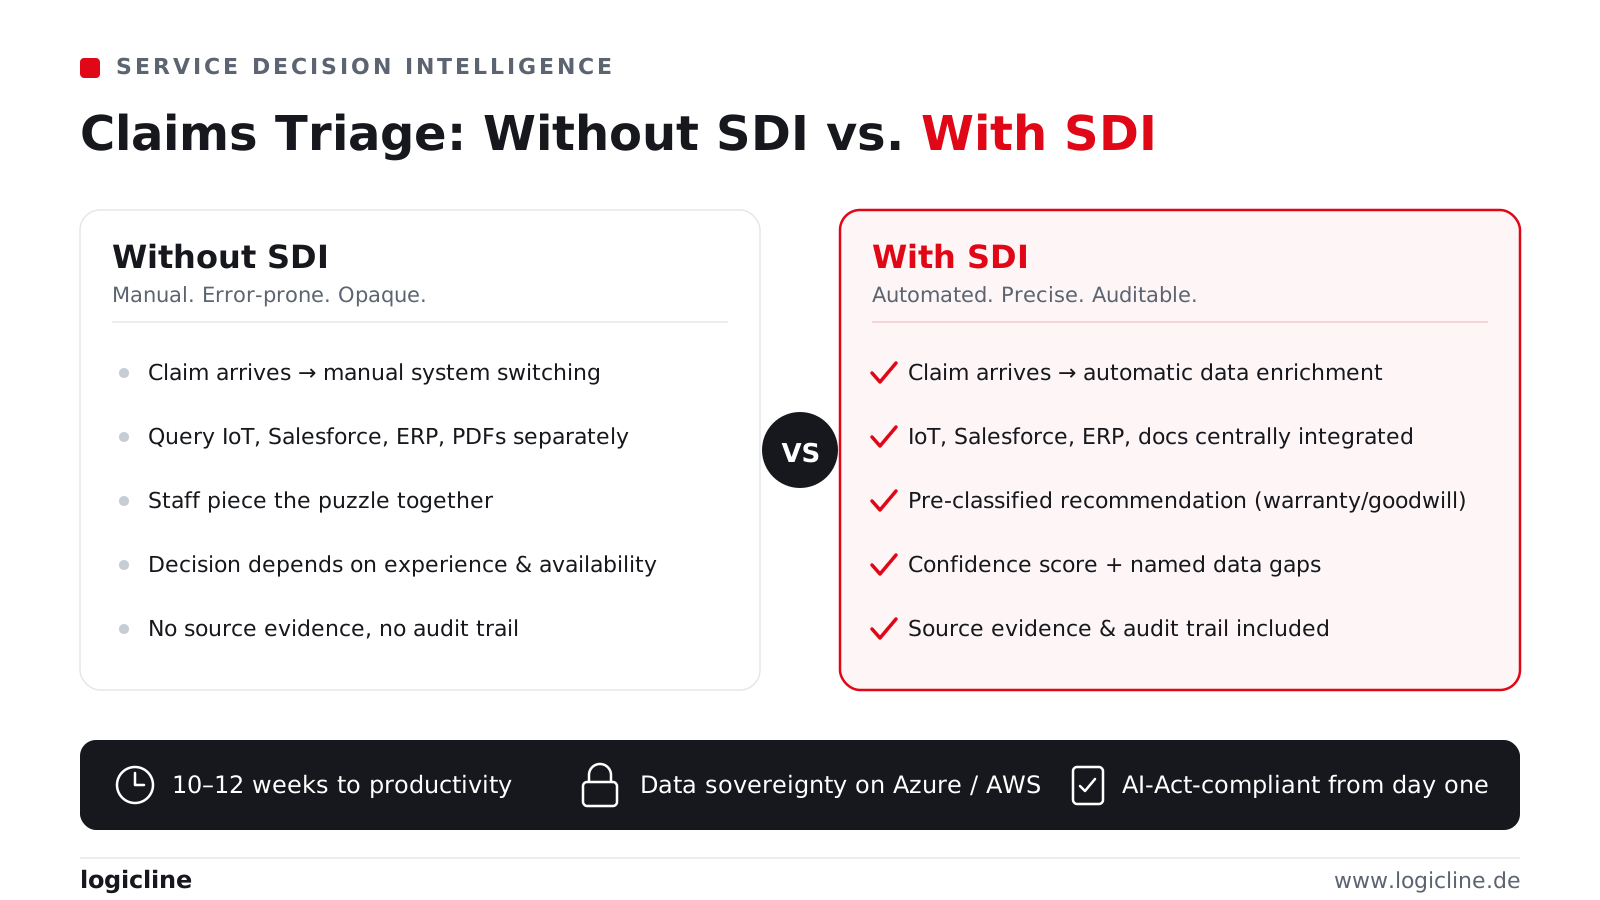
A complaint is reported. At first glance, it appears to be a warranty claim—but is that really the case? To clarify this, the employee in charge accesses various sources: IoT data, Salesforce, ERP systems, and PDF archives. Each of these sources provides only one piece of the puzzle, and there is no seamless connection between them.
The decision as to whether a case is classified under warranty, goodwill or as chargeable depends on whether an experienced employee compiles all the information correctly. Phone calls, email correspondence and the manual comparison of Excel lists characterize the daily work routine in many service organizations – even at manufacturers who have long since digitized their data.
When experienced employees leave the company, valuable knowledge is often lost. Using a generic LLM (Large Language Model) as a substitute carries risks: Such models may generate incorrect fault codes, misjudge contract terms, or suggest maintenance steps intended for other machines. In contrast, SDI offers reliable and fully integrated data preparation.
How SDI Is Changing Claims Triage
With SDI, a service case is automatically populated with relevant information right from the start: IoT telemetry data, contract details from Salesforce, material batches and warranty periods from the ERP system, as well as relevant sections from the technical documentation—all without having to manually switch between systems.
SDI provides a pre-classified recommendation—such as “warranty,” “goodwill,” or “subject to a fee”—supplemented by a confidence score and notes on potential data gaps. If, for example, proof of maintenance is missing, this is clearly indicated rather than presenting assumptions as facts. Each recommendation includes a source citation that makes it clear on what data the decision is based. This ensures that the solution is auditable from the outset and complies with the requirements of the AI Act.
The key difference is that people make the final decision – but on the basis of sound information, not in uncertainty.
An office worker asks a simple question in natural language: “Why has Machine 41788 been breaking down more frequently over the past six weeks?”
Without SDI, this means that tickets, IoT dashboards, and service documentation must be searched manually—with results that depend heavily on who is available at the time.
With SDI, on the other hand, the intelligence layer simultaneously analyzes IoT time series, open and closed tickets, and technical documentation. The result is a precise answer that includes a source citation, a confidence score, and clearly identified data gaps. This is not a “black box” response, but rather a citable diagnosis that transparently shows which sensor data was decisive, which ticket contains the relevant information, and which section of the operating instructions is affected. The inside sales staff can process this information directly.
It’s important to note that SDI acts as an intelligence layer between the data and the AI agent—it is not the front end itself, but rather the foundation for informed decisions.
In 30 minutes, we’ll determine where your service data isn’t yet integrated—and where SDI would come into play.
Using a specific service case from your machine fleet, we’ll show you which sources are currently missing and what a citable diagnosis—complete with a confidence score and source citations—would look like. This isn’t a generic AI pitch—it’s a look at your specific data situation.
→ Schedule an introductory call
8 Reasons Why SDI Protects AI Agents from Hallucinations
SDI offers eight clear advantages for preventing hallucinations by generic AI agents while enabling reliable, transparent decisions.
Confidence scores and named data gaps
While generic AI models often provide answers with apparent certainty, even when the data set is insufficient, SDI takes a different approach. Each recommendation includes a confidence score that transparently indicates the reliability of the statement. You can verify whether such a score is accurate: Of the recommendations with an 80 percent confidence score, about 80 percent should be correct. The article “How to Verify the Confidence Scores of a Service AI” explains how this works. In addition, SDI actively tests hypotheses for counterevidence. For example, if maintenance records are missing or sensor readings are incomplete, this is explicitly noted. This ensures that users can clearly understand the basis for the recommendation and identify where uncertainties exist.
Reliable AI must be able to acknowledge uncertainty—presenting assumptions as facts is more dangerous than honestly acknowledging data gaps. This is exactly the approach SDI takes.
Persistent audit trail and AI Act compliance from day 1
With SDI, every response is documented by an immutable audit trail. This trail shows exactly which sensor data, tickets, or ERP entries form the basis for a recommendation. Since the audit trail cannot be edited retroactively, it meets the transparency and traceability requirements of the EU AI Act from the very beginning. For heads of service, this means that every decision is fully auditable.
Cross-asset reasoning across fleets and locations
A single machine log is often not enough to get a comprehensive picture. SDI analyzes patterns across the entire installed base —regardless of locations, machine types, or operating environments. For example, if ten machines of a certain type exhibit similar anomalies within a specific time frame, SDI identifies these correlations. This enables fleet-wide analysis that goes far beyond individual case diagnostics and provides companies with centralized control over their data infrastructure.
Data sovereignty in Your Own Cloud
SDI runs directly on the customer’s infrastructure—either on Azure, AWS, or Heroku— not in a shared environment. As a result, service data, machine data, and contract histories remain within the customer’s own cloud and are not used in external LLM training. This solution not only meets industry-specific data protection requirements but also allows for flexible integration into existing systems.
LLM- and agent-agnostic via MCP
SDI is independent of any specific AI front end. Using the Model Context Protocol (MCP) —an open standard for connecting context sources to AI models—the intelligence layer can be connected to Agentforce, Claude, Copilot, or other agents. Even if the front end is changed, the entire domain logic—including the knowledge base, confidence logic, and audit trails—remains intact.
Headless 360 and Bidirectional Availability
The SDI functions are available both as a REST action for Agentforce and as an MCP tool for other AI front ends. Without proprietary formats or vendor lock-in, the same diagnostic logic can be used in parallel across different systems. The open architecture enables flexible and future-proof integration.
Pre-built skills instead of your own RAG infrastructure
Anyone who develops an AI diagnosis tool for their service in-house must first build the infrastructure: data connectivity, retrieval, and evaluation of responses. This ties up a project team for months before the first recommendation appears in the service. SDI comes with six pre-built skills tailored to the data model used by machinery and equipment manufacturers. You can test whether they work with your data in advance—over a period of three to four weeks—using completed service cases, before deciding whether to implement them.
An Overview of the Six SDI Skills
The six skills form a comprehensive intelligence layer for the machinery and equipment service:
| SDI Skill | Function |
|---|---|
| Telemetry analysis | Analysis of IoT time series |
| CRM Context via GRAX | Salesforce history without API limits—service cases, contracts, and complaints related to a machine spanning several years |
| ERP data | Material, batches, orders and warranty periods from the ERP |
| Technical Knowledge via RAG | Technical documentation becomes searchable via Retrieval Augmented Generation; logicline helped develop the Salesforce integration for Empolis Service Express |
| Diagnostic Synthesis | Claims, RMA, and Warranty Triage with Confidence Score, Cross-Asset Analysis, and Audit Trail |
| Proactive insights | Pattern recognition across the entire fleet for early recommendations for action |
For more details on the individual skills, please visit the SDI Services page.
SDI as the intelligence layer behind AI front ends
SDI vs. Generic AI Front Ends: The Roles of the Individual Layers
SDI lays the foundation for reliable front ends by seamlessly integrating data from various sources, such as IoT, Salesforce, ERP, and technical documentation. Front-ends like Agentforce or Copilot can produce erroneous results without a domain-specific knowledge base—not because of poor models, but because of a lack of structured data. A separate article explains why a generic AI assistant cannot answer the most important service question —because it lacks machine context. This is where SDI comes in: It acts as an intelligence layer that bridges this gap and processes data transparently.
A knowledge base provides the agent with external data—product details, service histories, fault codes—that it accesses for every response. Without this source, the LLM remains reliant on the statistical probability of its own training data. SDI’s strength lies in providing a robust knowledge base with source citations, confidence scores, and a permanent audit trail. While the front end remains flexibly interchangeable, SDI ensures stable, domain-specific logic.
This clear separation between the knowledge base and the front end facilitates integration into existing systems and ensures that the results remain reliable.
Native Salesforce data model instead of external overlays
SDI operates directly on the native Salesforce data model and does not require any additional overlays. It leverages existing structures such as asset hierarchies, service histories, and the installed base. Changes made in the CRM are reflected in the knowledge base in real time, without the need for additional synchronization logic.
One example of this is the Digital Machine File, which integrates configuration histories, the installed base, and IoT data directly into Salesforce. This approach eliminates the need for separate data transfers, and the information remains up to date at all times.
With this native approach, SDI offers not only real-time integration but also a high level of reliability, especially for industry-specific requirements.
Industry-specific precision and control over the infrastructure
Generic AI models are designed for general use cases and often lack specific knowledge related to machinery and equipment—such as details on fault codes, component generations, or maintenance cycles. SDI bridges this gap by providing precisely this information in a structured format and making it accessible to AI agents.
Another key advantage: SDI runs on the customer’s infrastructure—such as Azure or AWS—rather than in a shared environment. This ensures data sovereignty and meets the requirements of the AI Act. Service data remains protected and is not incorporated into external training models. Every response is based on a traceable and auditable dataset, ensuring maximum transparency.
This combination of domain-specific knowledge and strict infrastructure control is what fundamentally sets SDI apart from generic solutions.
SDI in logicline’s Service Architecture
Basis: The 4-step model
SDI is not being introduced as a standalone solution, but rather builds on the previous stages of the 4-step model:
- Step 1 — Digitize: The Digital Machine File in Salesforce creates a structured database.
- Phase 2 — Connect: The Installed Base Assessment consolidates and cleanses distributed master data; the IoT platform, ERP, and knowledge sources are connected to Salesforce.
- Stage 3 — Decide: SDI uses the connected data as a knowledge base and provides AI agents with answers that include source citations, confidence scores, and a persistent audit trail.
- Level 4 — Automate: Building on SDI, defined service tasks can be performed autonomously — the transition to Service as Software.
Without a complete and accurate machine profile and a consolidated installed base, any AI integration remains unreliable. This groundwork is crucial for efficiently integrating specialized partner solutions.
Integration of Partner Solutions: GRAX and Empolis Service Express
Two key partner solutions contribute significantly to SDI’s knowledge base.
- GRAX: This solution provides comprehensive access to Salesforce data histories—including service cases, contracts, and complaints—spanning multiple years—without being limited by API quotas. This gives the AI agent a complete overview of an object’s lifecycle, rather than just access to current data.
- Empolis Service Express: This is where technical documentation expertise comes into play. Using Retrieval Augmented Generation, users can perform targeted searches for manuals, fault codes, and maintenance instructions. logicline helped develop the Salesforce integration for Empolis Service Express, which combines technical knowledge and CRM data into a unified search logic. Our article, “Knowledge Management in Service,” takes an in-depth look at how this knowledge base is methodically built—from data entry in the ticket system to linking it to the machine file.
The Path to Automation: Level 4 and Service as Software
The implementation of SDI in Stage 3—Decide—lays the foundation for automation in Stage 4. Decisions that are currently reviewed and made by humans can be automated in the future. For example: If a decision’s confidence score exceeds a specified threshold, the same logic that currently notifies an employee can automatically trigger a service order in the future. SDI makes decisions not only machine-readable but also repeatable. This paves the way for a seamless transition to automation.
Conclusion: What SDI Means for Your Service Business
The most important findings
Without a domain-specific knowledge base, generic AI agents quickly reach their limits: The answers they provide are often unreliable and unverifiable—in claims or warranty triage, this leads to incorrect classifications and associated costs. This is exactly where SDI comes in and closes this gap.
With SDI, your service data is converted into a citable knowledge base. This includes source citations, confidence scores, and explicitly highlights existing data gaps. This ensures that decisions are based on well-founded and traceable information. SDI is a central component of the third stage— Decide —and paves the way for the gradual automation of your service processes.
Another advantage: SDI ensures your data sovereignty by using its own cloud infrastructure (Azure or AWS) and, thanks to the MCP architecture, remains independent of specific LLMs. The solution is directly AI-Act compliant and offers flexibility in system integration. The front end can be replaced, while the intelligence layer remains entirely under your control.
The first step is an honest review of your own data. Using the backtest, you can evaluate SDI on a specific machine type based on your closed service cases: Would the recommendation have been correct at the time, and how many cases actually have a documented cause? This takes three to four weeks, and the result may well be that it’s not a good fit yet. Go to the SDI product page. If machines, cases, and contracts are still spread across multiple systems today, the Installed Base Assessment is the better place to start.
